What we have learned modernizing with AI.
First-hand notes from the team building ARC: where business rules hide, what breaks when AI agents plan and build at scale, and how to tell a real result from a marketing number.
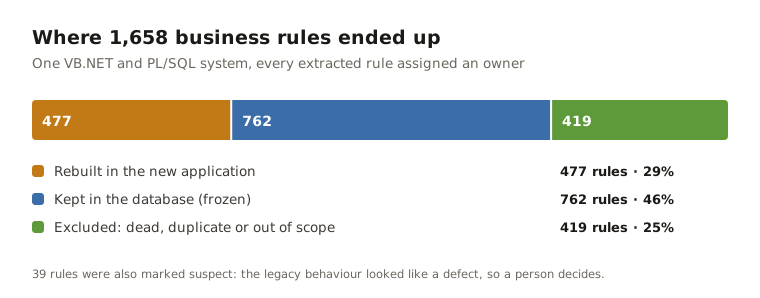
Where 1,658 business rules ended up
We extracted every business rule from a VB.NET and Oracle system and gave each one an owner. Only 29% belonged in the new code. Here is where the rest went.
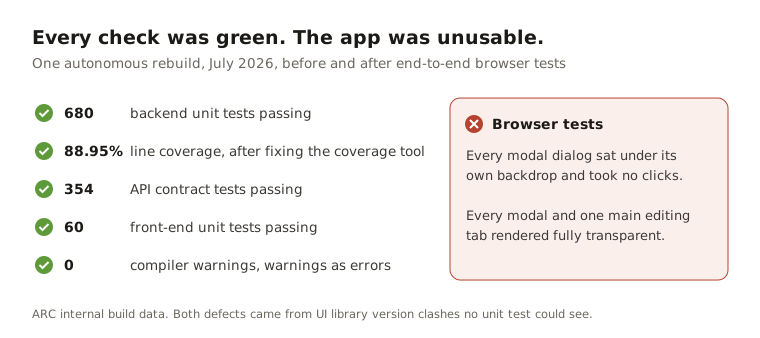
Our own tests said the rebuild was done. Every dialog was unclickable.
On one autonomous rebuild, every unit metric was green while the app was unusable. What that taught us about testing AI-built code, and what to measure instead.
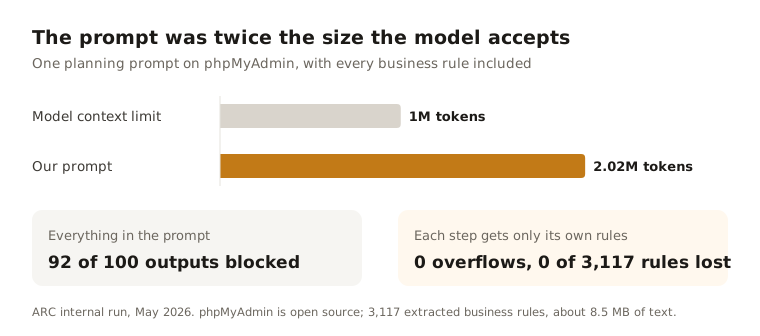
We gave the model everything. 92 of 100 outputs failed.
Putting a whole legacy system's rules into one prompt produced a 2-million-token request and 92 blocked outputs. What fixed it, and what it means for large codebases.
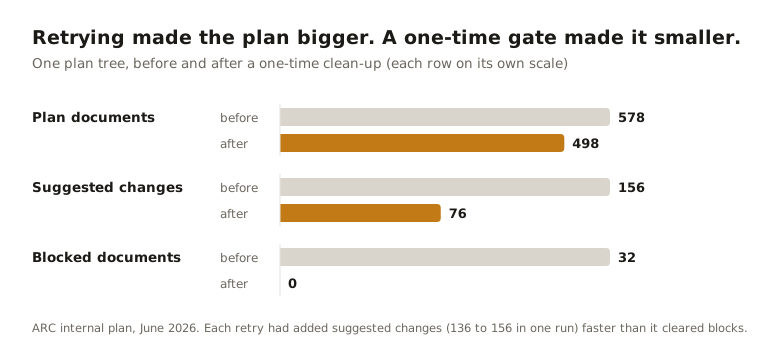
Our AI planner made more work every time we retried it
Pressing retry on an AI planning pipeline grew the plan instead of fixing it. The cause was unstable identities, and the fix was a one-time clean-up.
What AI code review catches, and what it doesn't
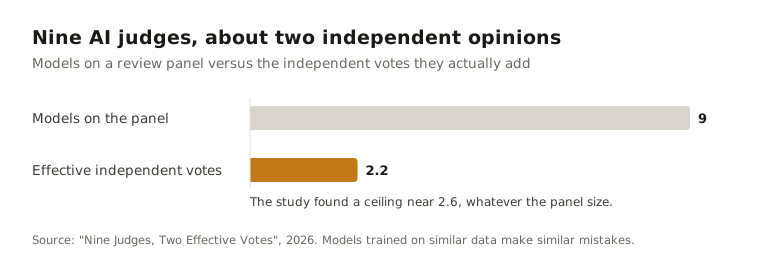
AI reviewers check the code our agents write. What the research says about AI judges, the false failures we saw, and why tests still decide.
What a SWE-bench score actually measures
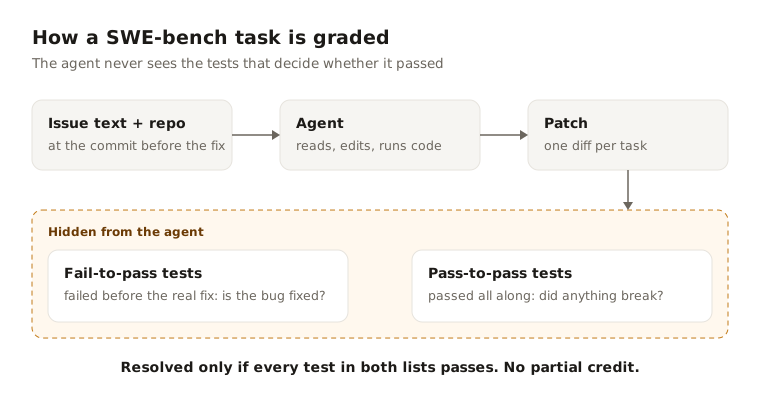
SWE-bench grades AI coding agents with hidden tests on small fixes. What a score tells you, why Verified was retired, and why SWE-bench Pro has the same problem.